About Me
I am Jiahao Tang. My research interests include Vision-Centric AI, Agentic Coding, and Vision-Language-Action (VLA) models.
I received my M.Sc. and B.Eng. degrees from Sun Yat-sen University. I am currently a Research Assistant at the CSU-JPG Lab, Central South University, under the supervision of Prof. Alex Jinpeng Wang.
My research primarily focuses on multimodal models, especially Vision-Language-Code Alignment. I am also interested in world models and VLA, and I am actively exploring the intersection of these areas.
🌟🌟 I am actively looking for PhD positions starting in Spring/Fall 2027.
News
- 2026.06: Our paper FlowInOne: Unifying Multimodal Generation as Image-In Image-Out Flow Matching was accepted to ECCV 2026.
- 2026.04: Our paper From Charts to Code: A Hierarchical Benchmark for Multimodal Models was accepted to ACL Main 2026.
- 2026.02: Our paper Residual Decoder Adapter was accepted to CVPR 2026.
- 2026.07: I joined CSU-JPG Lab as a Research Assistant.
- 2025.06: I received my M.Eng. degree in Electronic Science and Technology from Sun Yat-sen University.
Experience
Research Assistant, JPG Lab, Central South University
2025.07 – Present
Supervisor: Alex Jinpeng Wang
- Conduct research on the understanding, generation, and evaluation of large multimodal models (LMMs), with a focus on Vision-to-Code Generation and Vision-Centric multimodal generation.
- From Charts to Code: A Hierarchical Benchmark for Multimodal Models (ACL Main 2026, first author, accepted)
Proposed a user-interactive Chart-to-Code benchmark covering chart reproduction, chart editing, and long-table-to-chart generation; evaluated 29 models and designed a rubric-based evaluation pipeline measuring code executability, code correctness, and visual consistency. - FlowInOne: Unifying Multimodal Generation as Image-in, Image-out Flow Matching (ECCV 2026, first author, under review)
Proposed an image-in, image-out multimodal generation paradigm that converts text descriptions, spatial layouts, and editing instructions into visual prompts; built the VisPrompt-5M dataset and conducted experiments with Qwen-Image-Edit and the CrossFlow framework. - Residual Decoder Adapter: ID-Preserving Tokenizer Adaption for AR Text Rendering (CVPR 2026, co-author, accepted)
Investigated poor text rendering quality in VQ-VAE-based autoregressive unified models, identified visual tokenizer reconstruction as a key bottleneck, and validated RDA through systematic evaluation and ablation studies on Janus-Pro, Lumina-mGPT, and TAR.
Algorithm Intern, Guangdong Engineering Center for IoT Chips and Systems
Supervisor: Jianguo Hu 2022.05 – 2023.09
- Worked on software-hardware co-design algorithms for national and provincial research projects, including AI-assisted EDA for automatic analog IC layout optimization.
- Built data pipelines for analog circuit netlist parsing, graph-structured modeling, and topology feature extraction to support GNN-based circuit performance prediction and intelligent EDA tasks.
- Developed VQA systems based on CLIP, BERT, and BLIP for cross-modal semantic alignment and reasoning.
Algorithm Intern, Guangdong Provincial Key Laboratory of Advanced IC Design and Integration Technology
Supervisor: Jianguo Hu 2023.10 – 2025.03
- Built multimodal understanding systems with Qwen-VL, Whisper, and knowledge graph modules for cross-media intelligent understanding.
- Supported pedestrian action recognition and VideoQA by processing video data, fine-tuning spatio-temporal representation models, and evaluating model performance.
Selected Publications
* indicates equal contribution.
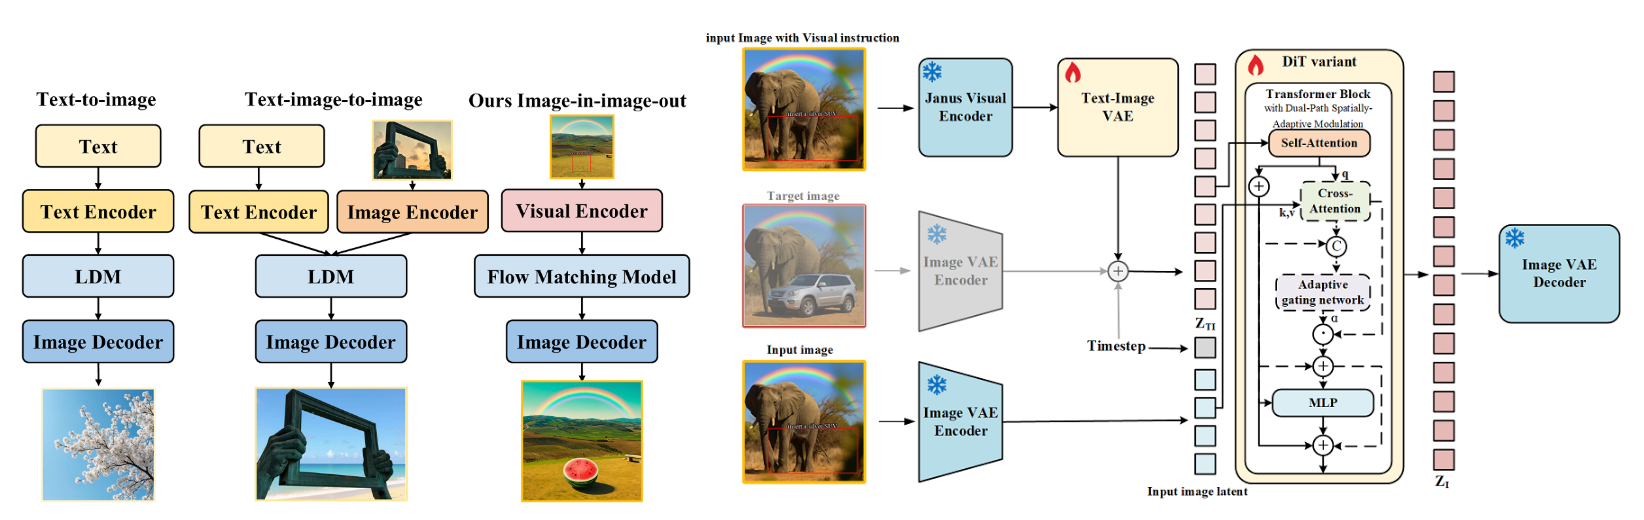
FlowInOne: Unifying Multimodal Generation as Image-in, Image-out Flow Matching
ECCV 2026
Junchao Yi*, Rui Zhao*, Jiahao Tang*, Weixian Lei, Linjie Li, Qisheng Su, Zhengyuan Yang, Lijuan Wang, Xiaofeng Zhu, Alex Jinpeng Wang.
[Project Page][arXiv][Github]
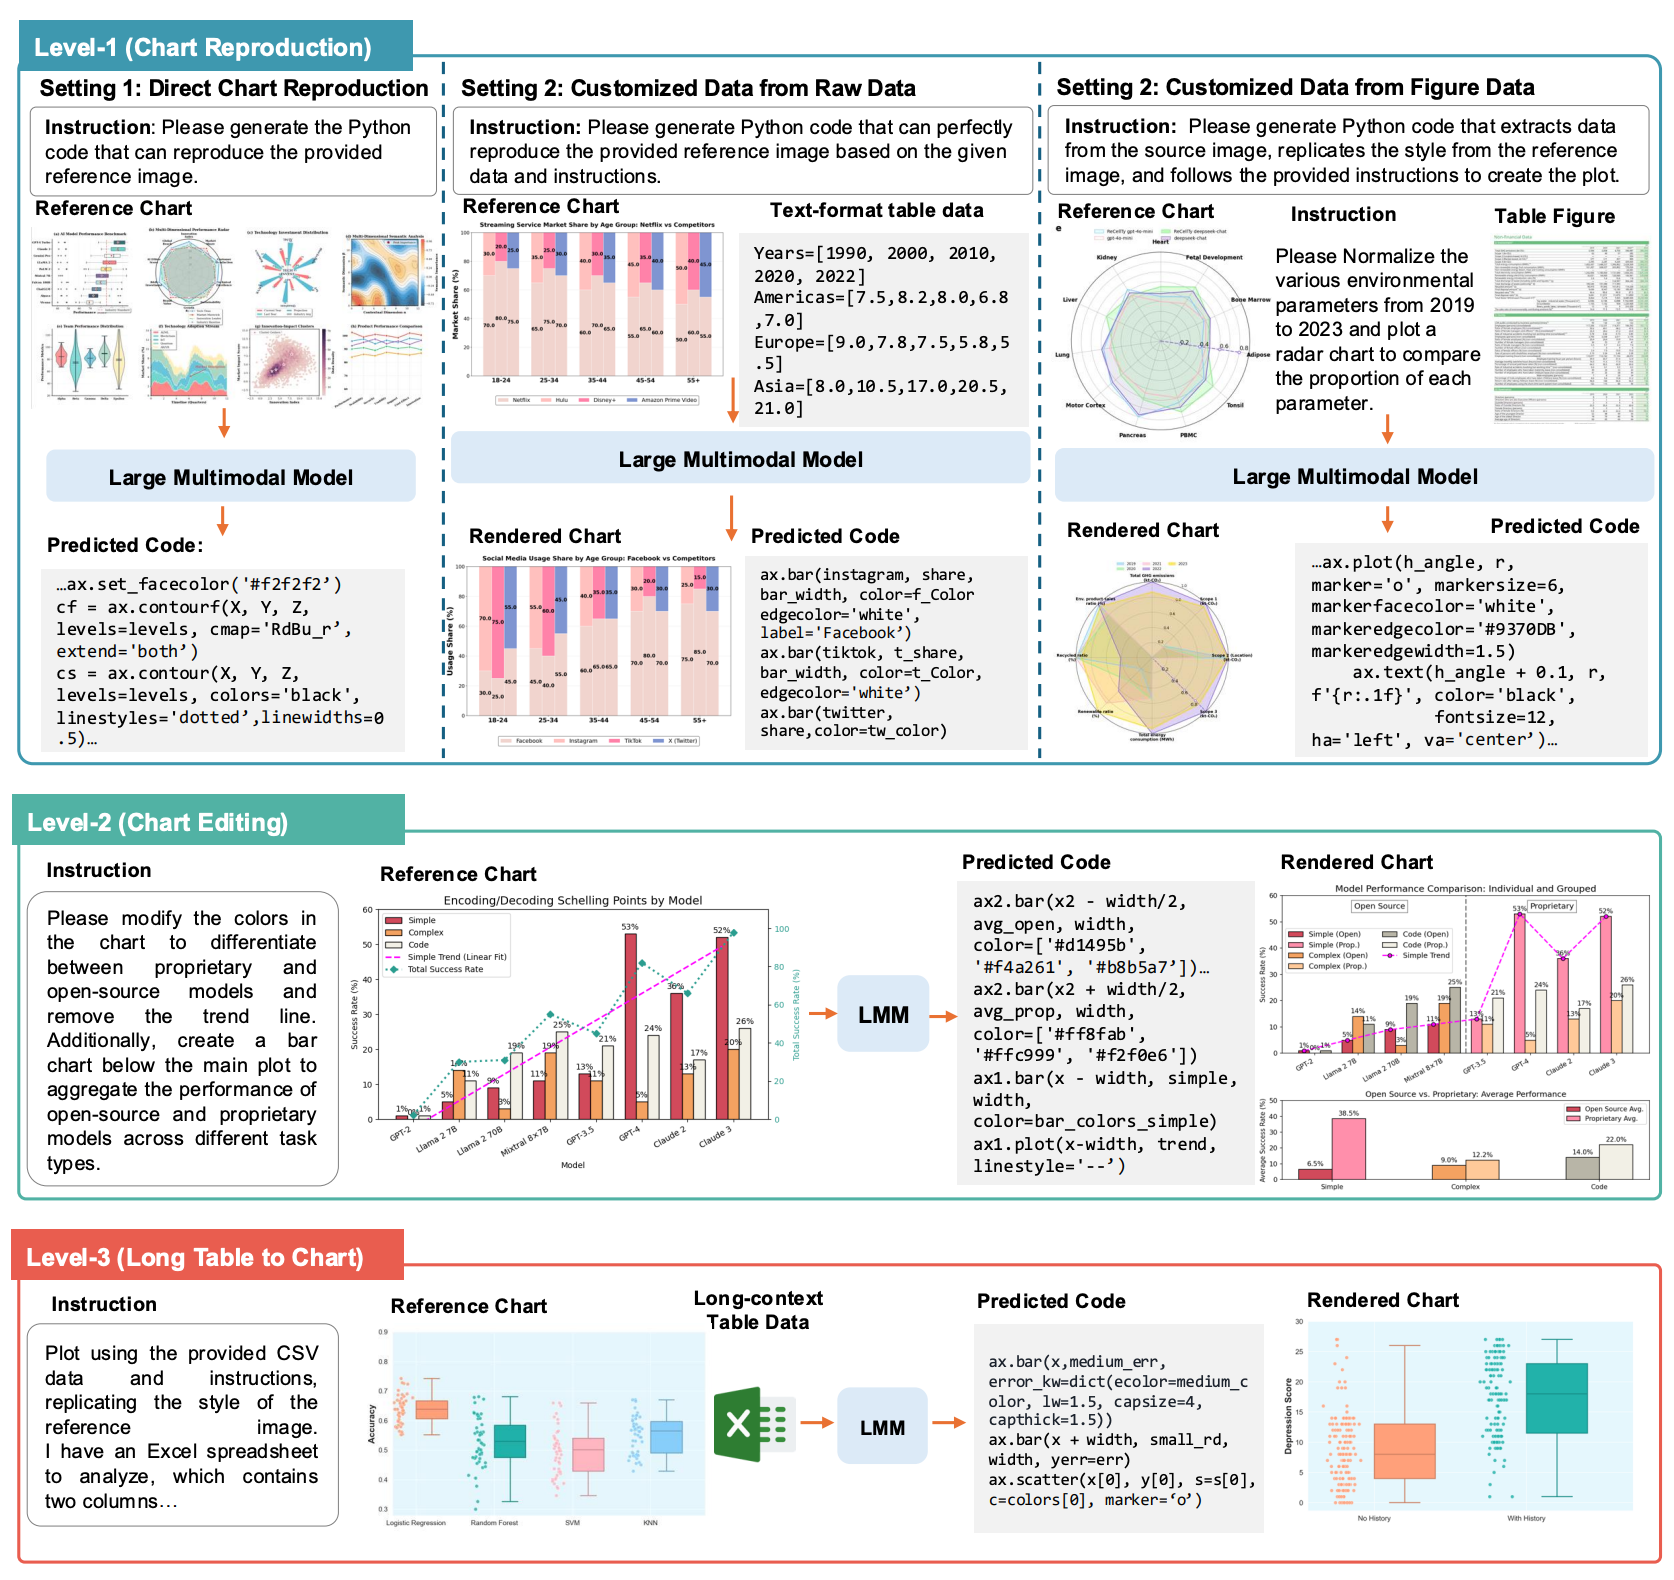
From Charts to Code: A Hierarchical Benchmark for Multimodal Models
ACL Main 2026
Jiahao Tang*, Henry Hengyuan Zhao*, Lijian Wu, Yifei Tao, Dongxing Mao, Yang Wan, Jingru Tan, Min Zeng, Min Li, Alex Jinpeng Wang.
[Project Page][arXiv][Github]
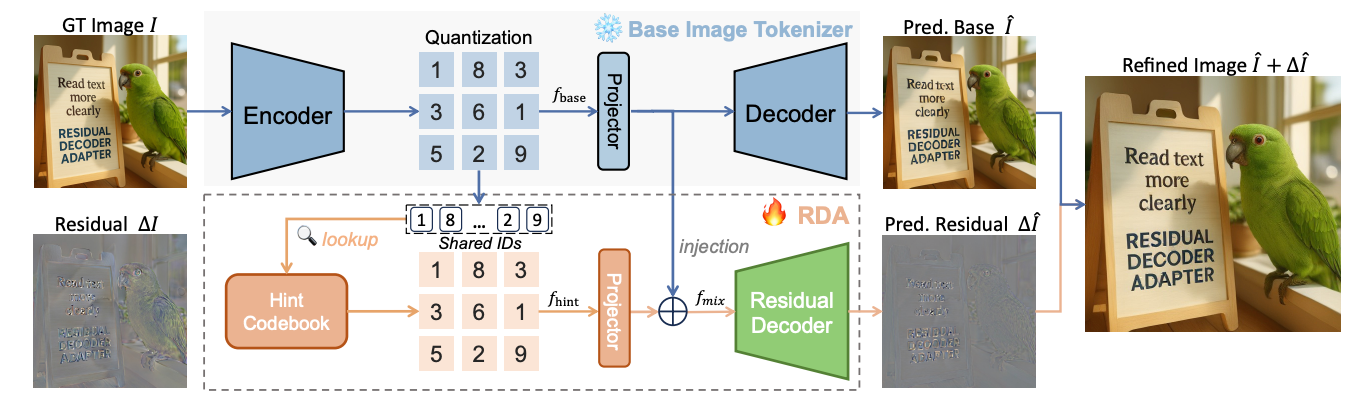
Residual Decoder Adapter: ID-Preserving Tokenizer Adaption for Autoregressive Text Rendering
CVPR 2026
Dongxing Mao*, Alex Jinpeng Wang*, Jiahao Tang, Kevin Qinghong Lin, Linjie Li, Zhengyuan Yang, Lijuan Wang, Min Li, Jingru Tan.
[Project Page][arXiv][Github]
Full Publications
- From Charts to Code: A Hierarchical Benchmark for Multimodal Models, Jiahao Tang*, Henry Hengyuan Zhao*, Lijian Wu, Yifei Tao, Dongxing Mao, Yang Wan, Jingru Tan, Min Zeng, Min Li, Alex Jinpeng Wang, ACL Main 2026. [Project Page][arXiv][Github]
- Residual Decoder Adapter: ID-Preserving Tokenizer Adaption for Autoregressive Text Rendering, Dongxing Mao*, Alex Jinpeng Wang*, Jiahao Tang, Kevin Qinghong Lin, Linjie Li, Zhengyuan Yang, Lijuan Wang, Min Li, Jingru Tan, CVPR 2026. [Project Page][arXiv][Github]
- FlowInOne: Unifying Multimodal Generation as Image-in, Image-out Flow Matching, Junchao Yi*, Rui Zhao*, Jiahao Tang*, Weixian Lei, Linjie Li, Qisheng Su, Zhengyuan Yang, Lijuan Wang, Xiaofeng Zhu, Alex Jinpeng Wang, ECCV 2026. [Project Page][arXiv][Github]
- ChartJudge: Evaluating Reward Models for LMM-based Chart-to-Code Generation, Lijian Wu*, Henry Hengyuan Zhao*, Zijian Zhang*, Jiahao Tang*, Jiajun Wu, Alex Jinpeng Wang, under review at ECCV 2026.
- Internalize External Competence for Visual Instruction Editing, Wenjun Huang*, Rui Zhao*, Suyang Hou*, Jiahao Tang, Wenjia Wang, Zhuobai Dong, Alex Jinpeng Wang, Hu Jian Guo, under review at NeurIPS 2026.
- Enhancing Visual Understanding in Multimodal Large Language Models with Efficient Feature Alignment and State Space Models, Wenjun Huang*, Jiakai Pan*, Jiahao Tang, Yifei Xing, Yuhe Wang, Zhengzhuo Wang, Shengzhi Shen, Jianguo Hu, ECAI 2025.
- VisCompConText: Scaling Multi-Modal Contexts via Visual Token Compression and Language Model Guidance, Wenjun Huang, Zhengzhuo Wang, Jiakai Pan, Yuhe Wang, Shengzhi Shen, Jiahao Tang, Chaoxing Zhou, Jianguo Hu, ECAI 2025.
- Spatio-Temporal Graph Convolution Transformer for Video Question Answering, Jiahao Tang, Jianguo Hu, Wenjun Huang, Shengzhi Shen, Jiakai Pan, Deming Wang, Yanyu Ding, IEEE Access 2024.
- Chinese Named Entity Recognition for IC Patent Domain Based on RoBERTa-wwm-ext, GCN and Efficient Global Pointer, Yunxiao Lin*, Jiahao Tang*, Wenjun Huang, Yanyu Ding, 2024 5th International Conference on Computing, Networks and Internet of Things.
Education
Sun Yat-sen University
M.Sc. in Electronic Science and Technology, 2022.09 – 2025.06
GPA: 3.8/4.0
Sun Yat-sen University
B.Eng. in Electronic Information Science and Technology, 2018.09 – 2022.06
GPA: 3.5/4.0
Skills
- Programming: Python, PyTorch, Verilog, C++, MATLAB, LaTeX.
- Hardware: Analog IC Design with Virtuoso, Digital IC Design with ModelSim, Antenna Design with HFSS.
- Languages: Mandarin Chinese, English.